
Use a spatio-temporal dataset when each datapoint has both a time and a geometry. This is useful for internal imagery catalogs, derived products, ground truth data, regions of interest, and processing outputs that need geospatial lookup.
This guide creates an imagery catalog from code. You will define the dataset schema with the Python SDK, reference the image files as assets, ingest geospatial metadata, and query the catalog by time, location, and custom fields.
Prerequisites
Section titled “Prerequisites”- You have a Tilebox API key.
- You have installed the Python SDK.
uv add tilebox geopandas shapelyDefine the catalog schema
Section titled “Define the catalog schema”Start by choosing the spatio-temporal dataset kind and the custom fields for your catalog. Tilebox adds the required time, id, ingestion_time, and geometry fields automatically.
The example catalog tracks imagery products with a provider product ID, file assets, cloud cover, and processing level. Field descriptions and example values become part of the generated schema documentation.
from tilebox.datasets import Clientfrom tilebox.datasets.data.datasets import DatasetKindfrom tilebox.datasets.schema import Assets
client = Client()
fields = [ { "name": "product_id", "type": str, "description": "Stable product or scene identifier from the source catalog.", "example_value": "LC08_L2SP_033033_20240808_20240814_02_T1", }, { "name": "assets", "type": Assets, "description": "Files associated with the imagery product.", }, { "name": "cloud_cover", "type": float, "description": "Cloud cover percentage for the product footprint.", "example_value": "3.2", "queryable": True, }, { "name": "processing_level", "type": str, "description": "Processing level or product type assigned by the source provider.", "example_value": "L2_SR", "queryable": True, },]Use field names that are stable and descriptive. Changing or removing fields after ingesting datapoints requires emptying the affected collections first, because existing datapoints must continue to match the dataset schema. The same rule applies to queryable fields: choose them before ingestion because you cannot make an existing field queryable or add a new queryable field to a non-empty dataset.
Create the dataset
Section titled “Create the dataset”Call create_or_update_dataset with the dataset kind, code name, field list, and display name. The code name becomes the stable identifier used in SDK calls.
dataset = client.create_or_update_dataset(    kind=DatasetKind.SPATIOTEMPORAL,    code_name="internal_imagery_catalog",    fields=fields,    name="Internal imagery catalog",)
print(dataset)If a dataset with the same code name already exists, create_or_update_dataset updates it instead of creating a duplicate. This makes the snippet safe to keep in a setup script.
Inspect the generated schema documentation
Section titled “Inspect the generated schema documentation”Tilebox uses the dataset kind and field annotations to document the schema. Required fields are added by the dataset kind, and your custom fields appear with their descriptions and examples.
For this catalog, the complete schema includes:
| Field | Type | Queryable | Purpose |
|---|---|---|---|
time | Required | Dedicated time filter | Timestamp associated with the datapoint. |
id | Required | Dedicated ID filter | Tilebox-generated UUID for the datapoint. |
ingestion_time | Required | No | Time when Tilebox ingested the datapoint. |
geometry | Required | Dedicated spatial filter | Geometry used for spatial queries. |
product_id | Custom | No | Stable product or scene identifier. |
assets | Custom | No | Files associated with the imagery product. |
cloud_cover | Custom | Yes | Cloud cover percentage for filtering. |
processing_level | Custom | Yes | Provider processing level or product type. |
The descriptions and example values you provided in the SDK call appear in the dataset schema documentation.
Add richer dataset documentation
Section titled “Add richer dataset documentation”Use field descriptions for schema-level documentation. Use the Console documentation editor when you want longer Markdown documentation for the dataset, such as provenance notes, quality caveats, ingestion rules, or examples for downstream users.
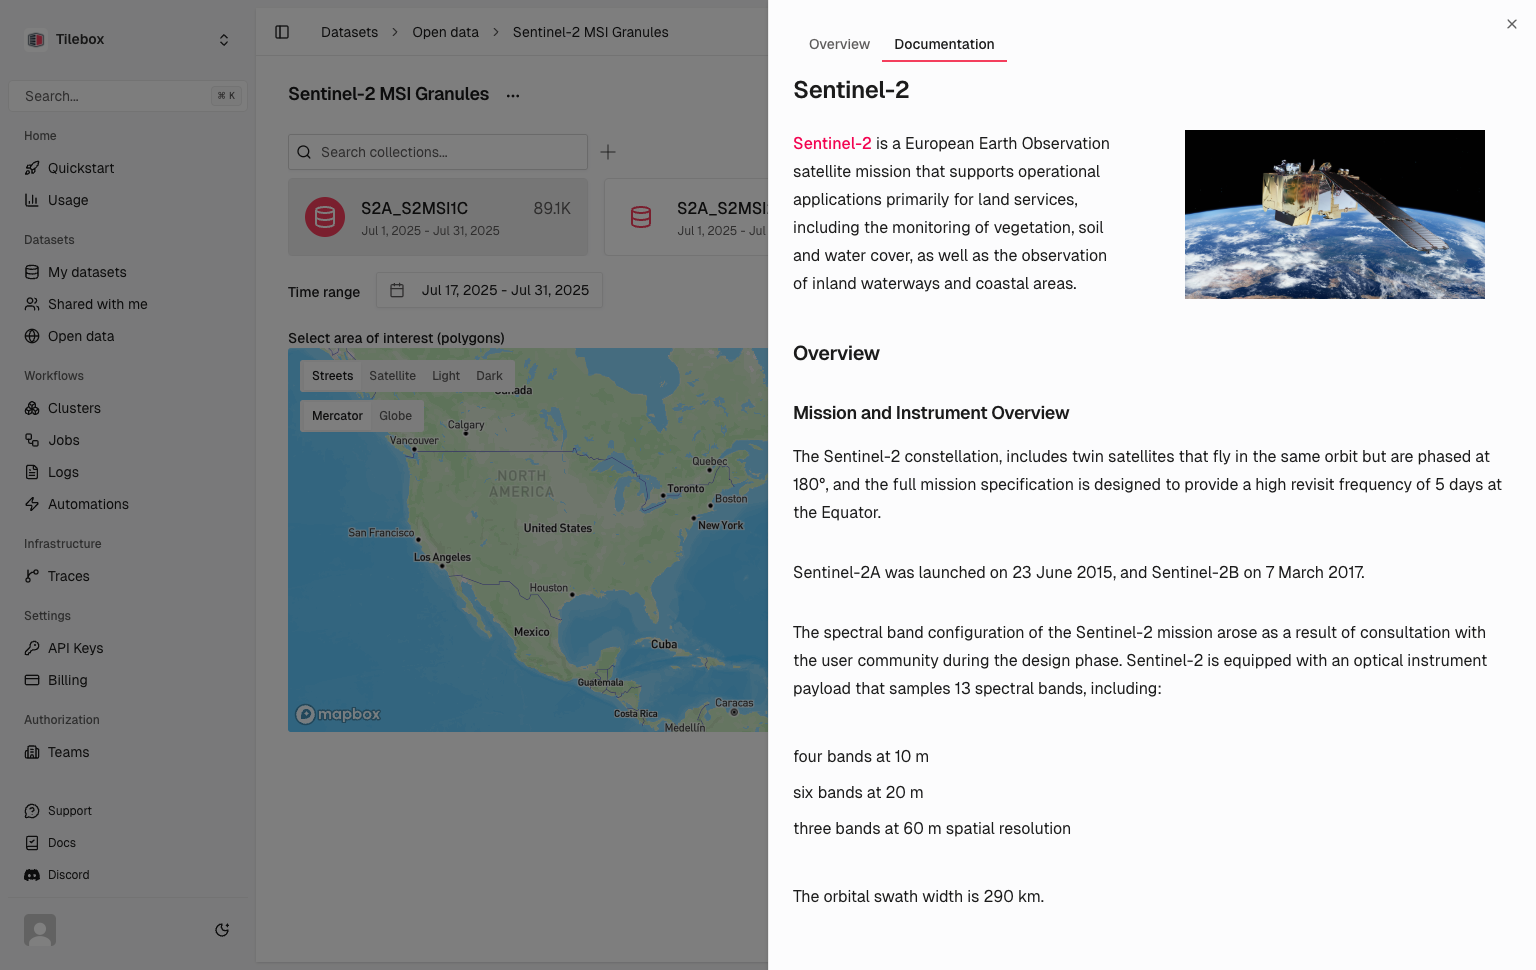
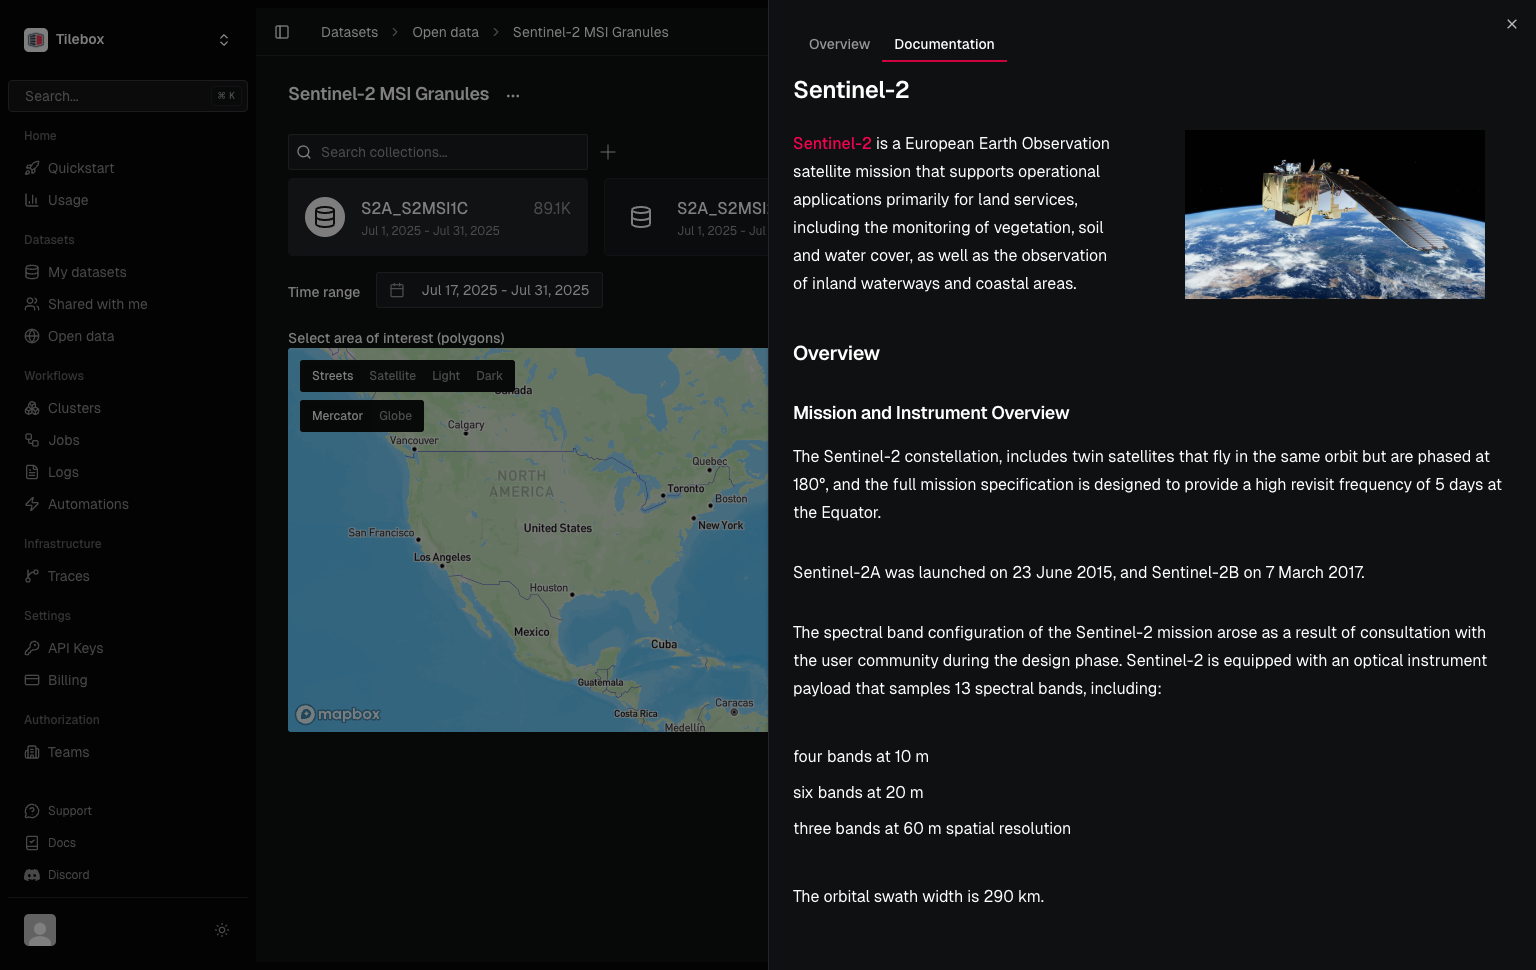
Open the dataset in the Console, click the edit pencil on the documentation section, and add Markdown content. A short documentation block often includes:
# Internal imagery catalog
This dataset indexes analysis-ready imagery products used by the operations team.
## Source
Products are copied from the provider archive after validation.
## Usage notes
Use `cloud_cover < 10` for workflows that require mostly cloud-free scenes.Create a collection
Section titled “Create a collection”After creating the dataset, create a collection to hold datapoints. Collections let you organize datapoints within the same schema, for example by provider, product family, or processing pipeline.
collection = dataset.get_or_create_collection("landsat_level_2")print(collection)Prepare datapoints
Section titled “Prepare datapoints”Load your source metadata into a GeoDataFrame. The geometry column should contain the footprint for each datapoint.
import geopandas as gpd
products = gpd.read_parquet("products.geoparquet")products = products.rename(    columns={        "timestamp": "time",        "scene": "product_id",        "path": "source_href",    })
products = products[ ["time", "geometry", "product_id", "source_href", "cloud_cover", "processing_level"]]Add asset references
Section titled “Add asset references”Convert each source file into an asset collection, then add its dataset fields to the record:
from tilebox.datasets.assets import Asset, AssetCollection, AssetLocation, MediaType
records = []for record in products.to_dict(orient="records"): source_href = record.pop("source_href") assets = AssetCollection.from_assets( [ Asset( key="image", primary=AssetLocation(source_href), media_type=MediaType.CLOUD_OPTIMIZED_GEOTIFF, roles=frozenset({"data"}), ) ] ) records.append({**record, **assets.to_fields()})AssetCollection.from_assets validates and normalizes the metadata into the structure consumed by the storage client. It does not upload the referenced file or test its availability.
Ingest the catalog
Section titled “Ingest the catalog”Ingest the prepared records into a collection.
collection.ingest(records)Query by time, location, and custom fields
Section titled “Query by time, location, and custom fields”After ingestion, combine the queryable custom fields with temporal and spatial filters. Tilebox applies all three filters on the server before returning matching datapoints.
from shapely import boxfrom tilebox.datasets import field
area = box(11.0, 46.0, 12.0, 47.0)
matches = collection.query( temporal_extent=("2026-01-01", "2026-02-01"), spatial_extent=area, filter=(field("cloud_cover") < 10) & (field("processing_level") == "L2_SR"),)Next steps
Section titled “Next steps”Learn the required fields and query behavior.
Filter by custom fieldsCombine queryable field expressions with temporal and spatial filters.
Ingest from common file formatsLoad CSV, Parquet, GeoParquet, and NetCDF data before ingestion.
Ingest into a spatio-temporal catalogPrepare GeoParquet metadata and ingest it into this catalog.